Self-host LLM vs cloud GPU rentals: where a home Mac cluster actually breaks even
Self-host LLM on a Mac Studio M3 Ultra and the per-month amortization lands at about $103 over 3 years. Break-even vs Groq Llama 70B at $0.59 per million tokens is 175 million tokens a month. At sustained 20 tok/s a single Mac produces 30 times that. The 4-node cluster math goes the other direction.
Self-host LLM vs cloud GPU rentals: where a home Mac cluster actually breaks even#
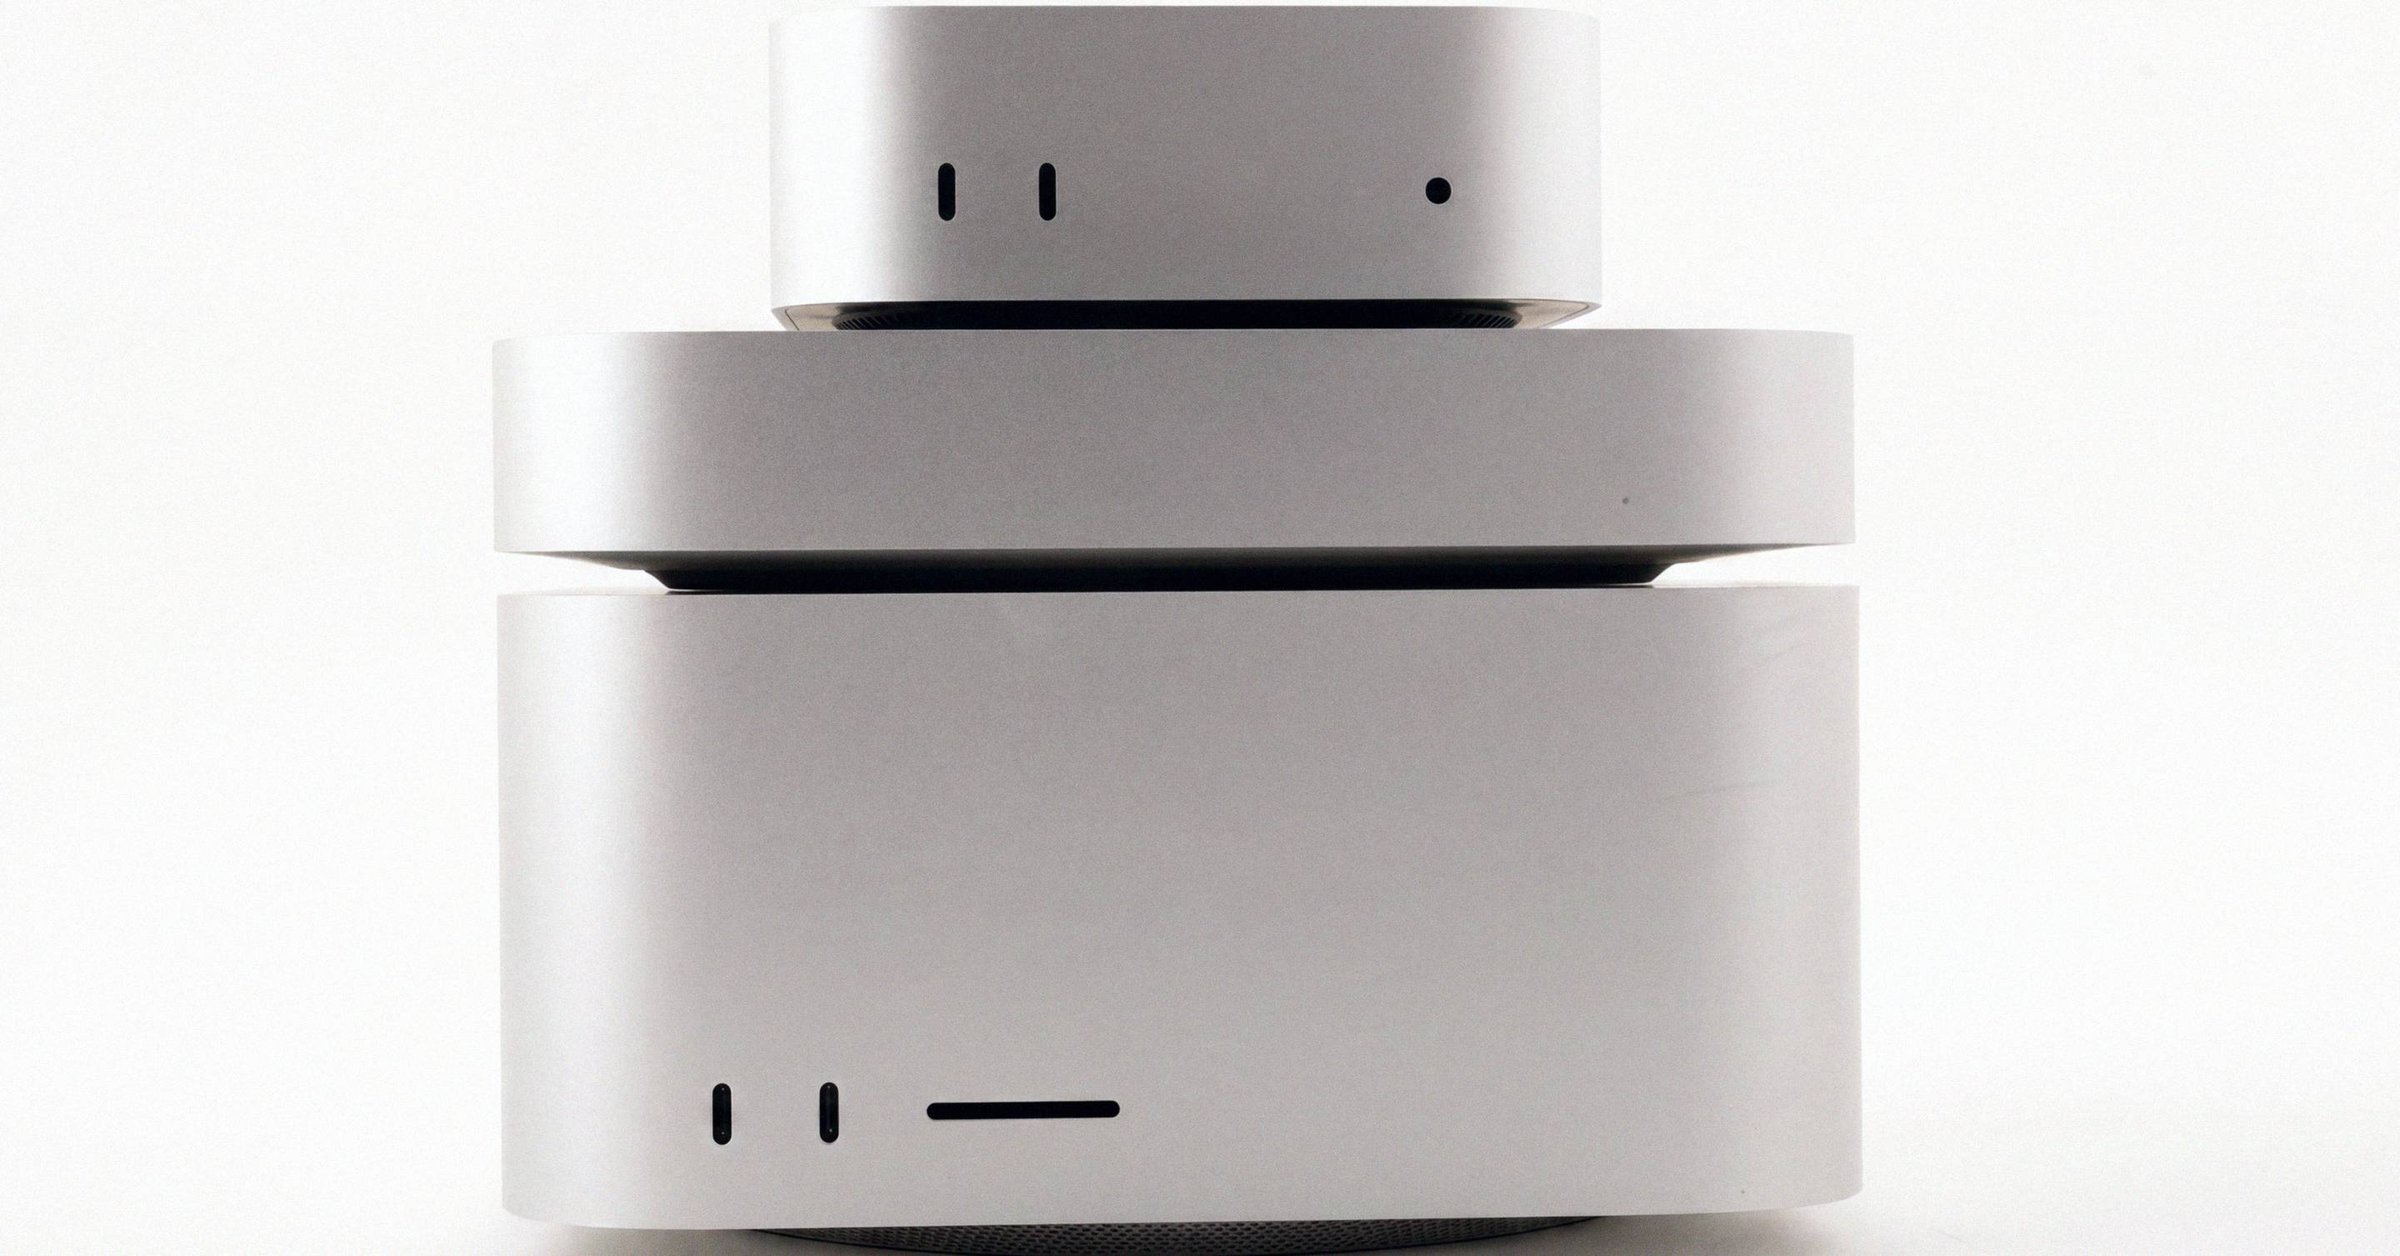
A single M3 Ultra Mac Studio 256 GB at $6,000 amortizes to about $103 a month over 3 years. Break-even versus Groq's $0.59-per-million-token Llama 70B endpoint is 175 million tokens per month. At a sustained 20 tok/s the Mac generates roughly 52 million tokens a day, 1.5 billion in a full month of continuous use. The break-even line is crossed in the first week of any reasonable duty cycle. The architectural context (how the home Mac cluster fits the workload at all) lives in the at-home Mac inference cluster reference for 2026; for what a Macfax diagnostic checks on the Mac itself before you commit to running it 24/7, see the diagnostic walkthrough.
The 4-node cluster math goes the other direction. A $40,000 build needs to generate 20 to 46 billion tokens a year to beat managed DeepSeek pricing at $0.30 to $0.70 per million tokens. At 32 tok/s single-stream the cluster has 1 billion tokens a year of single-user capacity, a 20x gap. The cluster earns its keep on capability and concurrency, not pure tokens-per-dollar.
This post does the numbers in both directions and pulls apart when each one applies.
The single-Mac break-even#
The amortization on a Mac Studio M3 Ultra 256 GB, base $6,000 net of trade-in or resale:
| Line item | 3-year total | Per month |
|---|---|---|
| Depreciation (50% residual against original) | $3,000 | $83 |
| Electricity (average draw ~150 W, 24/7, U.S. average $0.165/kWh) | $500 | $14 |
| AppleCare 3-year | $170 | $5 |
| Total | $3,700 | $103 |
The 50% residual assumption is not optimistic. A 2-year-old M2 Ultra Mac Studio 192 GB trades at $3,500 to $4,500 used against $4,800 original, which is closer to 75 to 90 percent retention at the 2-year mark. The M3 Ultra at 3 years should clear 50 percent comfortably unless DRAM oversupply suddenly resets the curve. The full $/GB-of-usable-memory picture (where the Mac wins by 3 to 27 times over NVIDIA at the same memory tier) backs this resale resilience.
Against managed Llama 70B endpoints at the May 2026 reference prices:
| Provider | $/M tokens | Break-even tokens/month vs $103 |
|---|---|---|
| Together.ai, Fireworks, DeepInfra (low) | 0.50 | 206 million |
| Groq | 0.59 | 175 million |
| Together / Fireworks / DeepInfra (high) | 0.90 | 114 million |
At 20 tok/s sustained on a 70B model, the Mac produces 1.728 million tokens per day per concurrent stream, or 52 million per day if you let it run agentically without idle gaps. Even at a 10 percent duty cycle the Mac clears 175 million tokens a month.
In other words: if you use it more than about an hour a day for real inference, the Mac is past Groq on pure token cost.
What the single-Mac break-even leaves out#
The amortization above understates the local win, because the managed endpoint is not selling you the same product:
- Model stability. Together, Fireworks, and DeepInfra can and do swap model versions and quantization regimes underneath their public endpoints. Local weights do not move.
- Privacy. Prompts and outputs stay in your machine. Many regulated industries (healthcare, legal, finance) cannot send payloads off-prem under their compliance posture.
- No rate limiting. Agentic loops that issue 10,000 calls in a session do not flag fraud heuristics or hit per-minute throttles.
- No metering anxiety. Iteration is free locally. On a metered endpoint a 100,000-turn prompt experiment is a real bill.
If you assign even a small dollar value to any of these, the local crossover shifts further left.
Reference cloud GPU prices, May 2026#
For workloads where you would otherwise rent raw GPU rather than hit a managed endpoint, the May 2026 prices look like this:
| GPU | On-demand $/hr | Spot $/hr | Effective $/M tokens (Llama 70B) |
|---|---|---|---|
| RTX 4090 (community) | $0.34 to $0.50 | $0.20 to $0.30 | ~$0.30 |
| RTX 5090 | $0.69 to $0.89 | $0.45 | ~$0.25 |
| A100 80 GB | $1.07 to $1.90 | $0.60 to $0.90 | ~$0.57 |
| H100 SXM (Spheron, low end) | $2.01 to $3.50 | $1.03 to $1.50 | ~$0.47 |
| H100 SXM (AWS on-demand) | ~$6.88 | n/a | $1.50+ |
| H200 | $2.50 to $4.00 | $1.50 | ~$0.70 |
| B200 SXM | $4.00 to $6.02 | $2.12 | ~$0.42 / $0.15 spot |
And the major managed endpoints:
- Together.ai, Fireworks.ai, DeepInfra: Llama 3.3 70B at $0.50 to $0.90 per million tokens; DeepSeek V3 at $0.30 to $0.70 per million tokens.
- Groq (LPU hardware): Llama 70B at hundreds of tokens per second, around $0.59 per million tokens.
- Cerebras Inference: Llama 70B at 2,000+ tok/s, around $0.85 per million tokens.
Spheron and RunPod sit at the low end of the spot curve for community-grade hardware. AWS sits at the high end of on-demand because of the surrounding compliance and orchestration overhead. The H100 SXM number does not include data transfer, persistent storage, or orchestration time.
The cluster math: $40K, 4 nodes, three years#
For trillion-parameter or DeepSeek-class workloads that exceed single-Mac capacity, the comparison is between a 4x M3 Ultra cluster and managed DeepSeek pricing.
| Line item | Annual |
|---|---|
| Hardware amortization ($40,000 / 3 years) | $13,333 |
| Electricity (4-node, average ~400 W, 24/7, U.S. average) | $580 |
| Total | ~$13,900/yr |
Against managed DeepSeek V3 pricing at $0.30 to $0.70 per million tokens, the break-even token volume is:
| Provider price | Tokens/year to break even |
|---|---|
| $0.30 (low) | 46.3 billion |
| $0.50 (midpoint) | 27.8 billion |
| $0.70 (high) | 19.9 billion |
At 32 tok/s single-stream (the EXO + RDMA result on DeepSeek V3.1 671B with a 4x M3 Ultra cluster), single-user capacity is about 1 billion tokens a year. Against the low-price managed endpoint that is a 46x utilization gap; against the high-price endpoint it is 20x.
The cluster cannot close that gap on single-stream alone. It closes it three ways:
- Concurrency. EXO with pipeline parallelism scales aggregate throughput nearly linearly with concurrent requests. Eight to sixteen simultaneous tenants on a 4x M3 Ultra cluster bring aggregate token rate closer to 200 to 400 tok/s, which lands the math in striking distance of break-even against managed endpoints.
- Capability. Many enterprise-edge customers buy the cluster to run a specific frontier model locally at all, not because cost-per-token beats Together. Healthcare and legal data-residency mandates are the most common driver.
- Privacy and audit. Cluster output never crosses the network boundary. For some buyers this is the entire economic case and the per-token math is incidental.
For a single developer iterating on personal projects, the 4-Mac cluster does not pay back against DeepInfra at $0.30 per million tokens. It is a capability investment, not a cost optimization.
Where the math actually points#
The single Mac Studio is the cleanest local cost case in 2026. A user who runs models more than a small fraction of the day already beats cloud on managed-endpoint pricing, with the local advantages (privacy, no rate limits, frozen weights) thrown in.
The 4-node cluster lives in a different category. It is justified by:
- Running a model that no single machine fits (DeepSeek V3.1 671B, Kimi K2 Thinking, Llama 3.1 405B with headroom).
- Serving multiple concurrent tenants or agent swarms whose aggregate token rate pays back the cluster on aggregate throughput.
- Operating under data-residency constraints that take cloud off the menu entirely.
- Wall-plug economics that no NVIDIA build matches at the same memory tier: a 4x M3 Ultra cluster fits on a standard 15 A residential circuit without electrician work; the multi-H100 equivalent does not.
Outside those three cases the cluster is more rig than economics. That is fine; some workloads earn the rig.
When cloud is the correct answer#
The mirror-image cases where the local Mac is the wrong choice:
- Bursty workloads with long idle periods. A request every 30 minutes that wants 30 tokens of output beats any local TCO. Pay the metered endpoint, save the capital.
- One-off capability bursts. A weekend fine-tune that needs H100 batched throughput. Spot-rent and shut it down. The cluster does not exist for this.
- Pre-purchase uncertainty. If the duty cycle stays low for more than the first quarter, the amortization assumption collapses and the cloud-per-token math wins by default.
Specifically: if you are unsure how often you will actually run inference, start on managed endpoints. The cost of being wrong about Mac utilization is $6,000 to $40,000 of capital and the depreciation curve. The cost of being wrong about cloud is the next monthly bill, which you can stop with one toggle.
What this means for the reader#
If you already know you will run inference for hours a day, buy the single Mac Studio M3 Ultra. The break-even line crosses inside the first month of normal use, and the local advantages compound from there. The 50 percent residual assumption is conservative on current Apple Silicon resale data, which means the true monthly amortization is likely lower than $103.
If you want trillion-parameter capability locally, build the 4-node cluster but do not pretend it is a cost optimization. The cluster pays back on capability and on aggregate throughput across multiple tenants, not on single-user token cost against DeepInfra. The honest framing is that the cluster buys privacy, control, and the ability to iterate on the largest open models without metering. That is a real product. It is not the same product as cheap tokens.
If your workload is bursty and your data is not regulated, stay on cloud. The math does not pretend otherwise.
Buying a Mac? Every listing on the Macfax shelf shows the exact configuration and an asking price in the open, with a signed report where the seller ran the checks.
Related posts
Mac LLM cluster: the complete 2026 guide to home Mac inference
Mac LLM cluster reference for 2026. Two December 2025 changes (RDMA over Thunderbolt 5 in macOS 26.2 and EXO 1.0) put trillion-parameter inference inside a 1 kW residential envelope. A 4-node M3 Ultra Mac Studio cluster runs Kimi K2 Thinking at 25 tok/s for under $40,000.
The 512GB M3 Ultra Mac Studio: a discontinued-capability premium
The 512GB M3 Ultra Mac Studio was discontinued in March 2026. Verified secondary sales now clear from $9,500 sealed to over $21,000, because no other consumer machine can hold a frontier-class local LLM in one box.
Mac Studio M3 Ultra trade-in vs eBay: a $4,000 channel spread
Mac Studio M3 Ultra 256/2TB pulls roughly $2,400 from Apple Trade In and $5,200 to $6,800 from eBay sold listings in 2026. Here is why the channel spread is the widest on any Mac sold today.
Written by
David ChenDavid Chen covers Apple Silicon for Macfax. He benchmarks local LLMs on M-series Macs and writes about unified-memory bandwidth, MLX, GGUF, prompt-eval throughput, and the tradeoffs between Mac and discrete-GPU inference. He has contributed to r/LocalLLaMA since 2023 and has run hundreds of model-and-quantization combinations across M1 Pro through M3 Ultra hardware on his own bench.
More posts by David →